Benchmark
Design samples and protocols that examine individual facts and the relationships between them.
Evaluation grounded in tasksFrom evaluation to execution environments.
AI built for work that matters.
Select a layer to explore its role in the system.
We study factuality and tool use, and translate domain expertise into executable workflows. Research informs the methods; real tasks test the results.
Design samples and protocols that examine individual facts and the relationships between them.
Evaluation grounded in tasksUse retrieval, fact decomposition and embedding alignment to examine differences between claims and evidence.
Check claims against evidenceConnect tools, acceptance criteria and recovery procedures to real workflows.
Make expertise executable
A workspace for everyday coding, with installation and sign-in built in. Review files and changes on the web, or keep working in the terminal.
Discover Lucky Code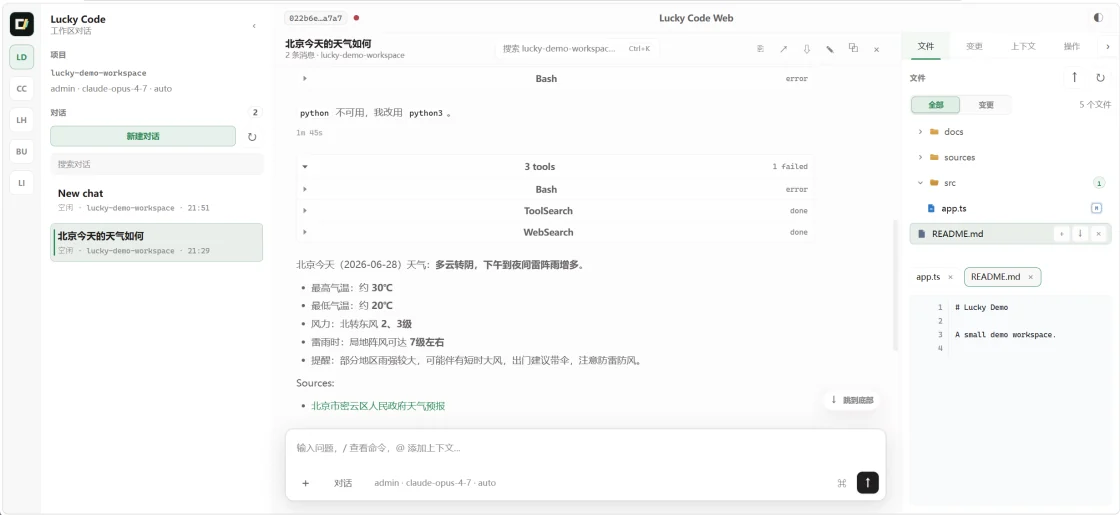
Tell us about your work, your data and the problem you want to solve.
Start a conversation